Optical Character Recognition System for Sinhala
Name of the Researcher(s)
- Dr. A.R. Weerasinghe
- Mr. Harsha Wijayawardhana
- Mr. Chamila Liyanage
Description
Optical Character Recognition (OCR) is a technology that has been widely researched over the past three decades with commercial systems available for English and other languages with Latin-based character sets. The application of OCR to non-Latin character sets has been increasingly successful more recently especially with initiatives such as Google’s Tesseract project. In particular some Indic languages have benefited and reported significant results in performance.
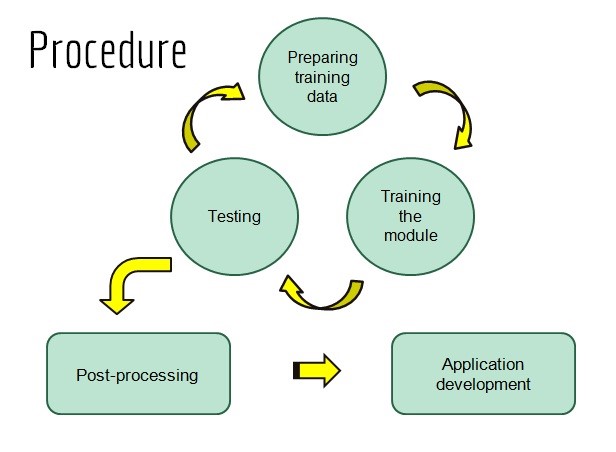
The availability of OCR technology would provide the basis for a range of other applications including information access to the visually impaired (used in tandem with a text-to-speech system), editability of scanned document images, reprinting of out-of-print publications, creating e-books for libraries and the book industry, and augmenting document management systems. Our main goal of this project is to develop the tools needed to automatically recognize the most common printed Sinhala fonts from scanned images of books and documents for digitizing such content. At the end of this project a user-friendly software tool to automate the process of digitizing scanned images of books and documents will be developed.
Tesseract, the Google OCR engine will be used as the framework for this project. Tesseract is an open source OCR engine that runs on various operating systems such as Linux, Windows and Mac OS. It supports several languages including English, French, Italian, German, Spanish, Brazilian, Portuguese and Dutch, among others. Since Tesseract is considered an accurate OCR engine, and having experienced using this framework developing an OCR system for Tamil, we use Tesseract with other technical aspects for this project.
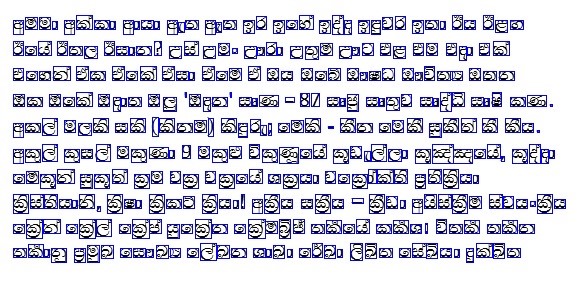
Related Images
Contact details of the researcher(s)
- Dr.A.R.Weerasinghe Email: arw@ucsc.cmb.ac.lk
- Mr. Harsha Wijayawardhana Email: harsha@bit.lk
- Mr. Chamila Liyanage
Publication
- Thilini Nadungodage, Ruvan Weerasinghe, and Mahesan Niranjan (2013). “Efficient use of training data for sinhala speech recognition using active learning.” Advances in ICT for Emerging Regions (ICTer), 2013 International Conference on. IEEE, 2013.
- Thilini Nadungodage, Viraj Welgama, Ruvan Weerasinghe (2013). “Developing a Speech Corpus for Sinhala Speech Recognition”. 10th International Conference on Natural Language Processing. CDAC, NOIDA, India, 18-20 December 2013.
- Thilini Nadungodage, Ruvan Weerasinghe, and Mahesan Niranjan (2015). “Speaker Adaptation Applied to Sinhala Speech Recognition”. Selected for publication in a special issue of the journal Research in Computing Science.
- Thilini Nadungodage, Ruvan Weerasinghe, and Mahesan Niranjan. “Application of Two Active Learning Methods in the Domain of Speech Recognition”. Submitted to the Computer Speech and Language Journal (Under Review).